上下文檢索是一種透過解決一個根本問題來提升 RAG 管線準確度的技術:當您將文件拆分成區塊時,每個區塊都會失去與更廣泛文件上下文的連結。
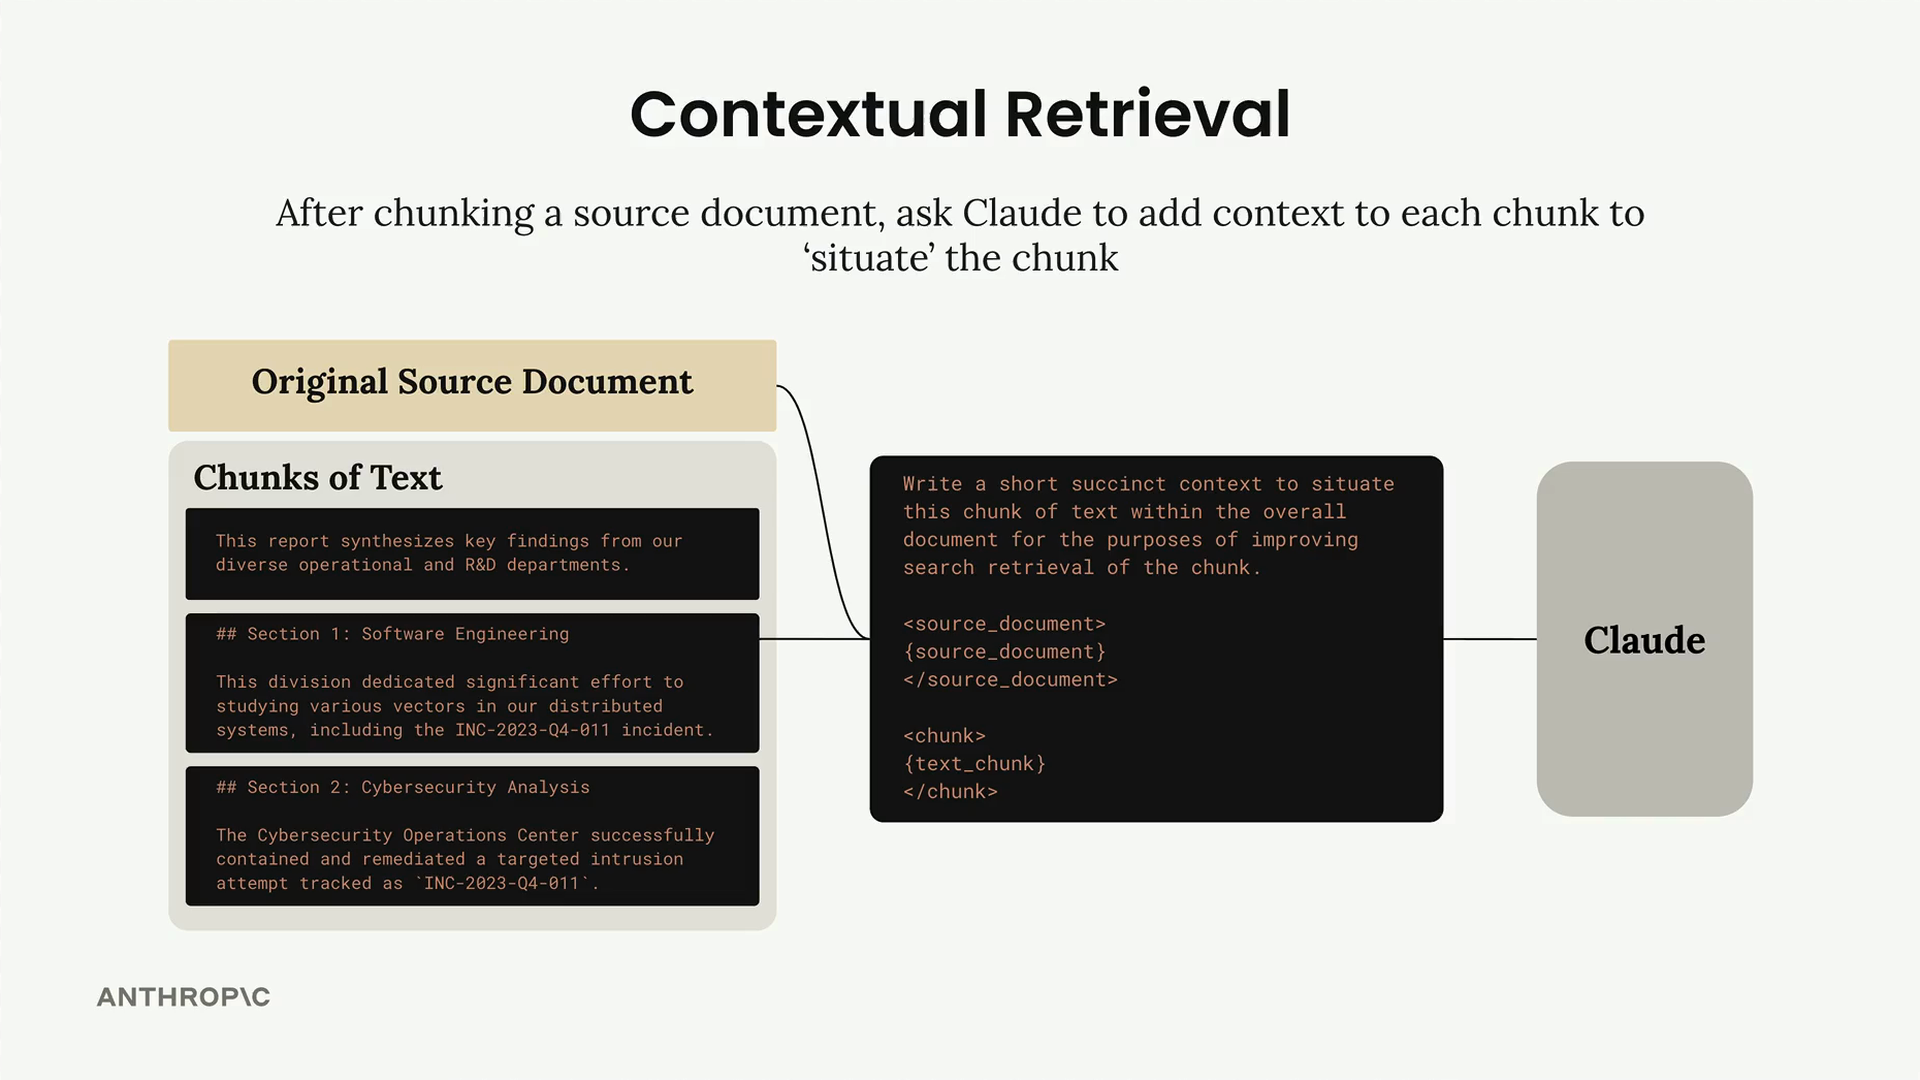
基本概念很簡單。在對來源文件進行分塊後,您要求 Claude 在將每個區塊儲存到您的檢索器資料庫之前,為其添加上下文。這個預處理步驟有助於將每個區塊「定位」在更大的文件中。
運作方式
對於每個文字區塊,您會將該區塊與原始來源文件一起傳送給 Claude,並附上類似這樣的提示:
Write a short and succinct snippet of text to situate this chunk within the
overall source document for the purposes of improving search retrieval of the chunk.

Here is the original source document:
<document>
{source_text}
</document>

Here is the chunk we want to situate within the whole document:
<chunk>
{text_chunk}
</chunk>

Answer only with the succinct context and nothing else.Claude 可能會生成如下的上下文:「本節摘自一份關於跨學科團隊的較大報告。其中提及 INC-2023-04-011,該編號也在網路安全分析章節中被提及。」
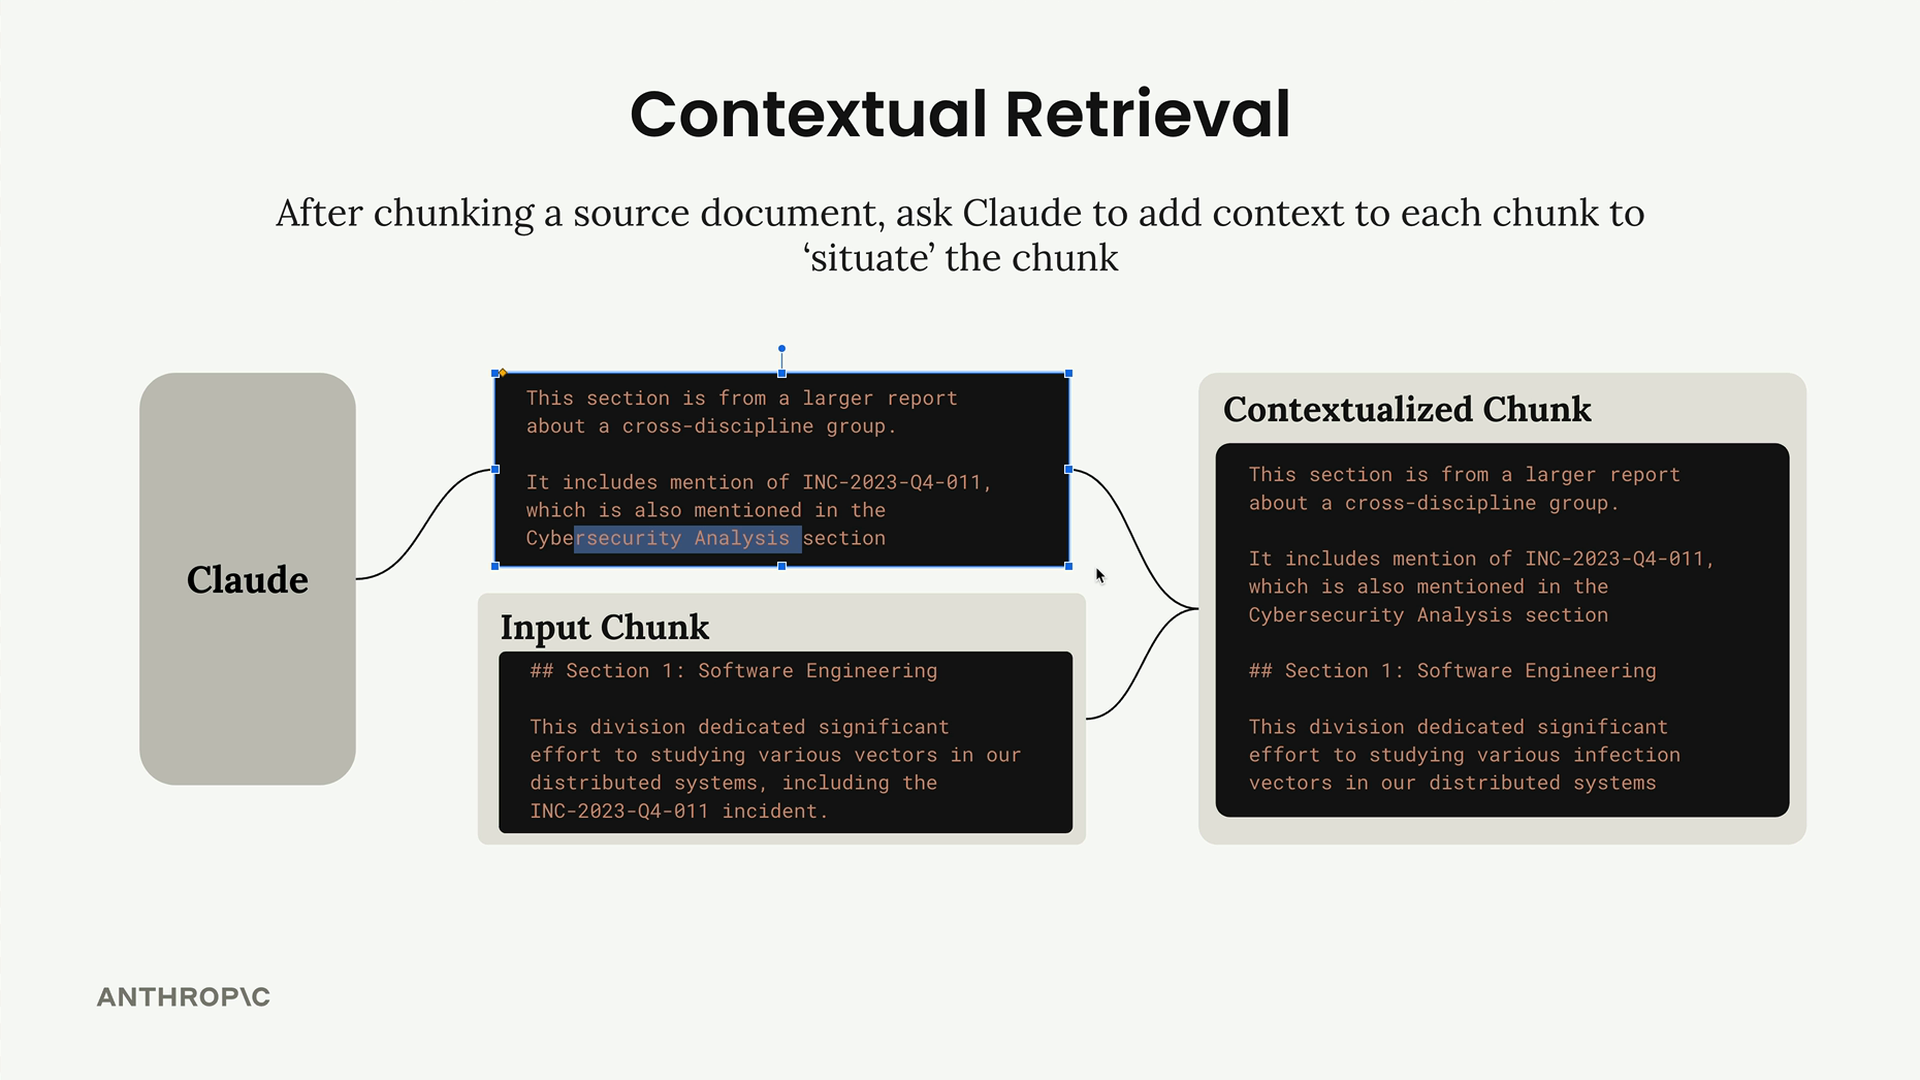
接著,您將這段生成的上下文與原始區塊文字結合,建立一個「上下文化區塊」,並將其儲存到您的向量索引和 BM25 索引中。
處理大型文件
如果您的來源文件太大,無法放入單一提示中,您可以提供精簡版的上下文,而非整份文件。
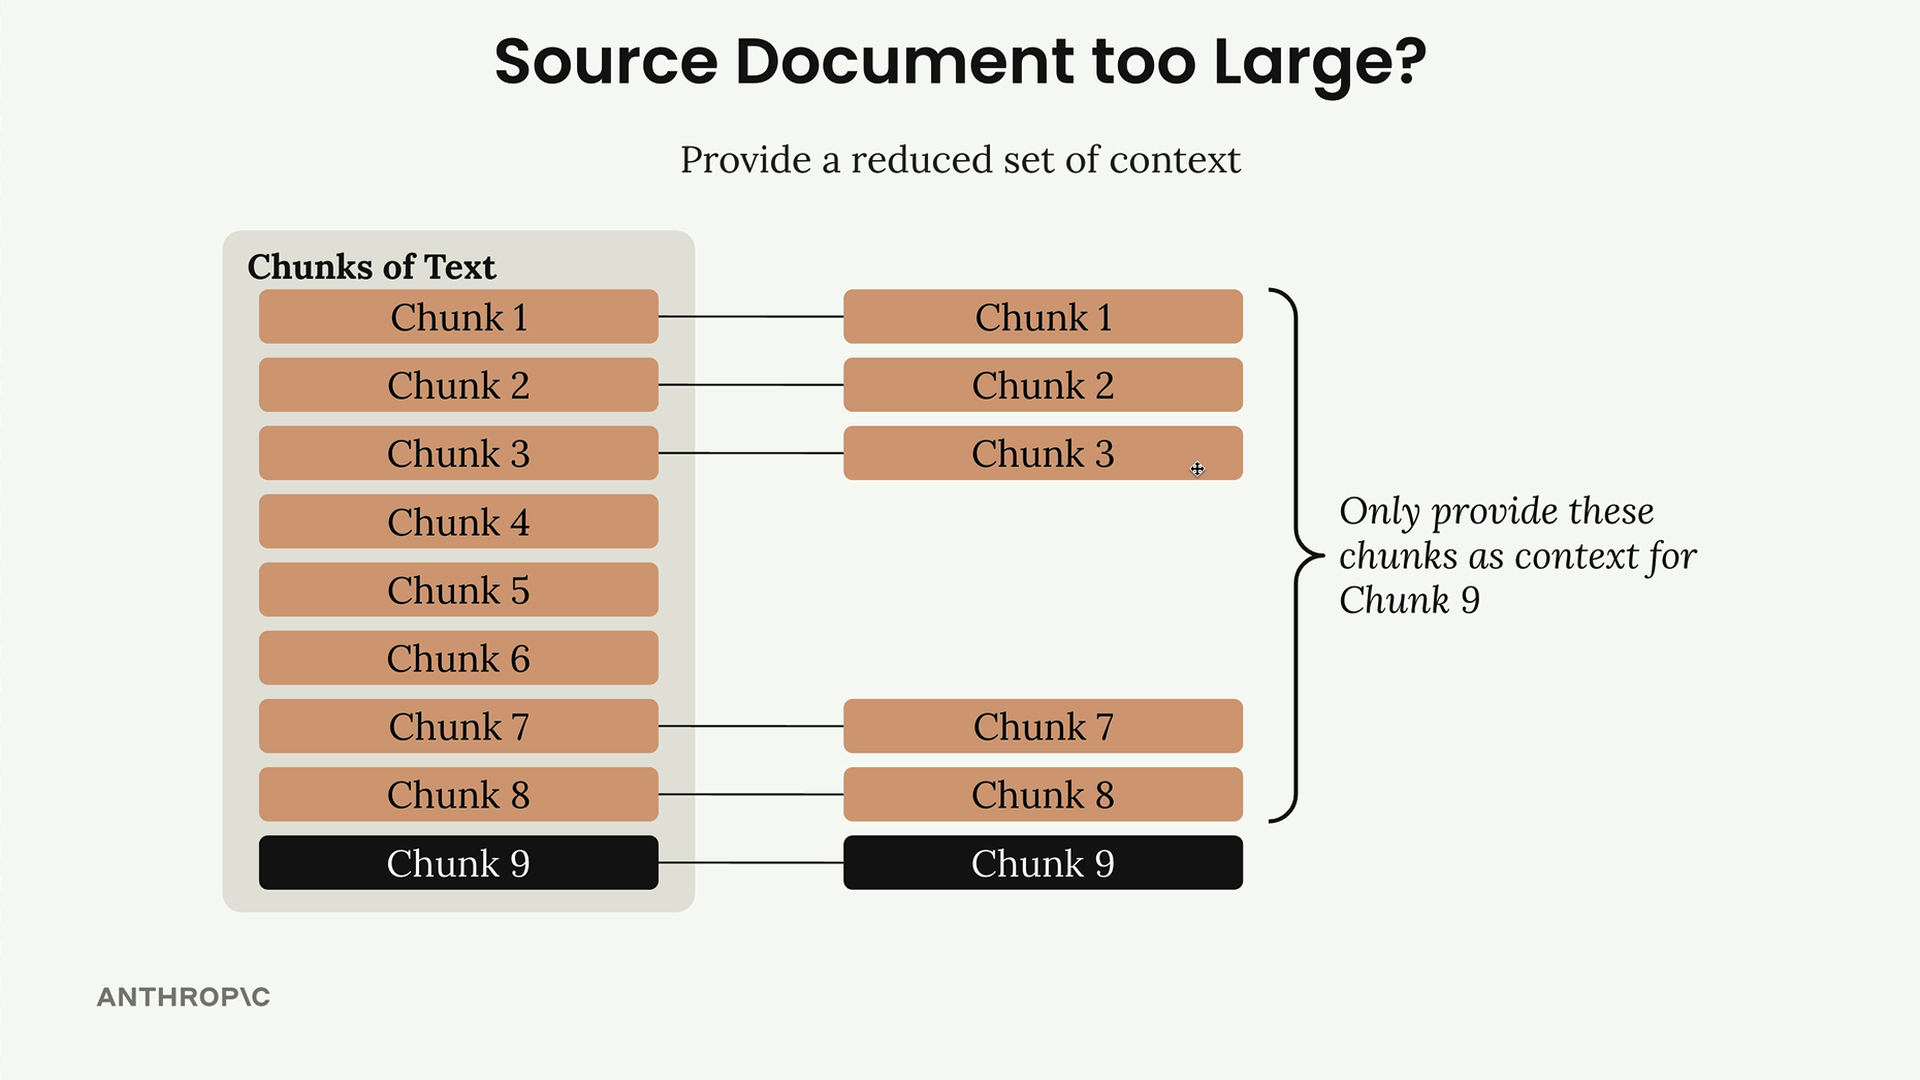
對於您要進行上下文化的任何給定區塊,請包含:
- 文件開頭的幾個區塊(通常包含摘要或概要)
- 緊接在目標區塊之前的區塊(提供局部上下文)
這種方法為 Claude 提供了足夠的資訊來生成有意義的上下文,而不會讓整份文件淹沒提示內容。
實作範例
以下是上下文檢索函式的基本實作:
def add_context(text_chunk, source_text):
    prompt = f"""
    Write a short and succinct snippet of text to situate this chunk within the
    overall source document for the purposes of improving search retrieval of the chunk.

    Here is the original source document:
    <document>
    {source_text}
    </document>

    Here is the chunk we want to situate within the whole document:
    <chunk>
    {text_chunk}
    </chunk>

    Answer only with the succinct context and nothing else.
    """

    messages = []
    add_user_message(messages, prompt)
    result = chat(messages)

    return result["text"] + "\n" + text_chunk
在處理您的文件區塊時,您會逐一遍歷每個區塊並生成上下文化版本:
# 為每個區塊加入上下文,然後加入檢索器
for i, chunk in enumerate(chunks):
    # 從起始區塊與前面的區塊建立上下文
    context_parts = []
    context_parts.extend(chunks[:min(num_start_chunks, len(chunks))])

    start_idx = max(0, i - num_prev_chunks)
    context_parts.extend(chunks[start_idx:i])

    context = "\n".join(context_parts)

    contextualized_chunk = add_context(chunk, context)
    retriever.add_document({"content": contextualized_chunk})
預期結果
生成的上下文提供了關於文件結構與關係的寶貴資訊。例如,Claude 可能會將某個區塊描述為「年度跨學科研究評論的第 2 節,詳細說明軟體工程團隊為解決鳳凰專案(Project Phoenix)穩定性問題所做的努力。該節緊接在方法論章節之後,財務分析章節之前,是涵蓋組織內十個研究領域的綜合報告的一部分。」
這些額外的上下文有助於檢索系統更好地理解每個區塊不僅包含什麼內容,還能理解它如何融入更大的文件結構,以及與其他章節的關聯。雖然對於簡單文件您可能不會看到顯著的改善,但隨著文件變得更加複雜,包含錯綜複雜的交叉引用和章節間的相依關係,上下文檢索的價值會愈來愈高。